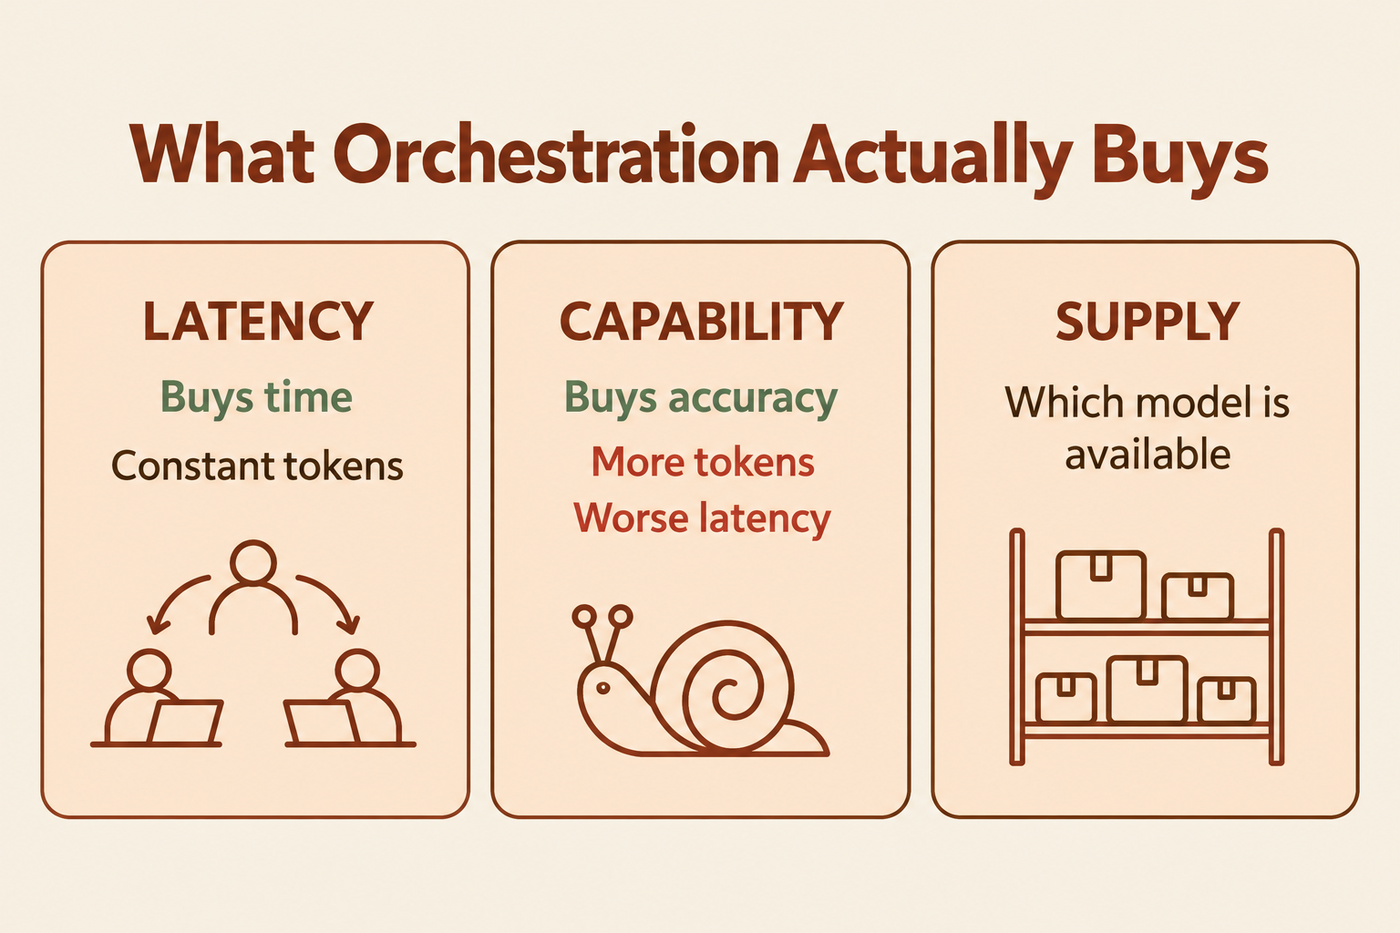
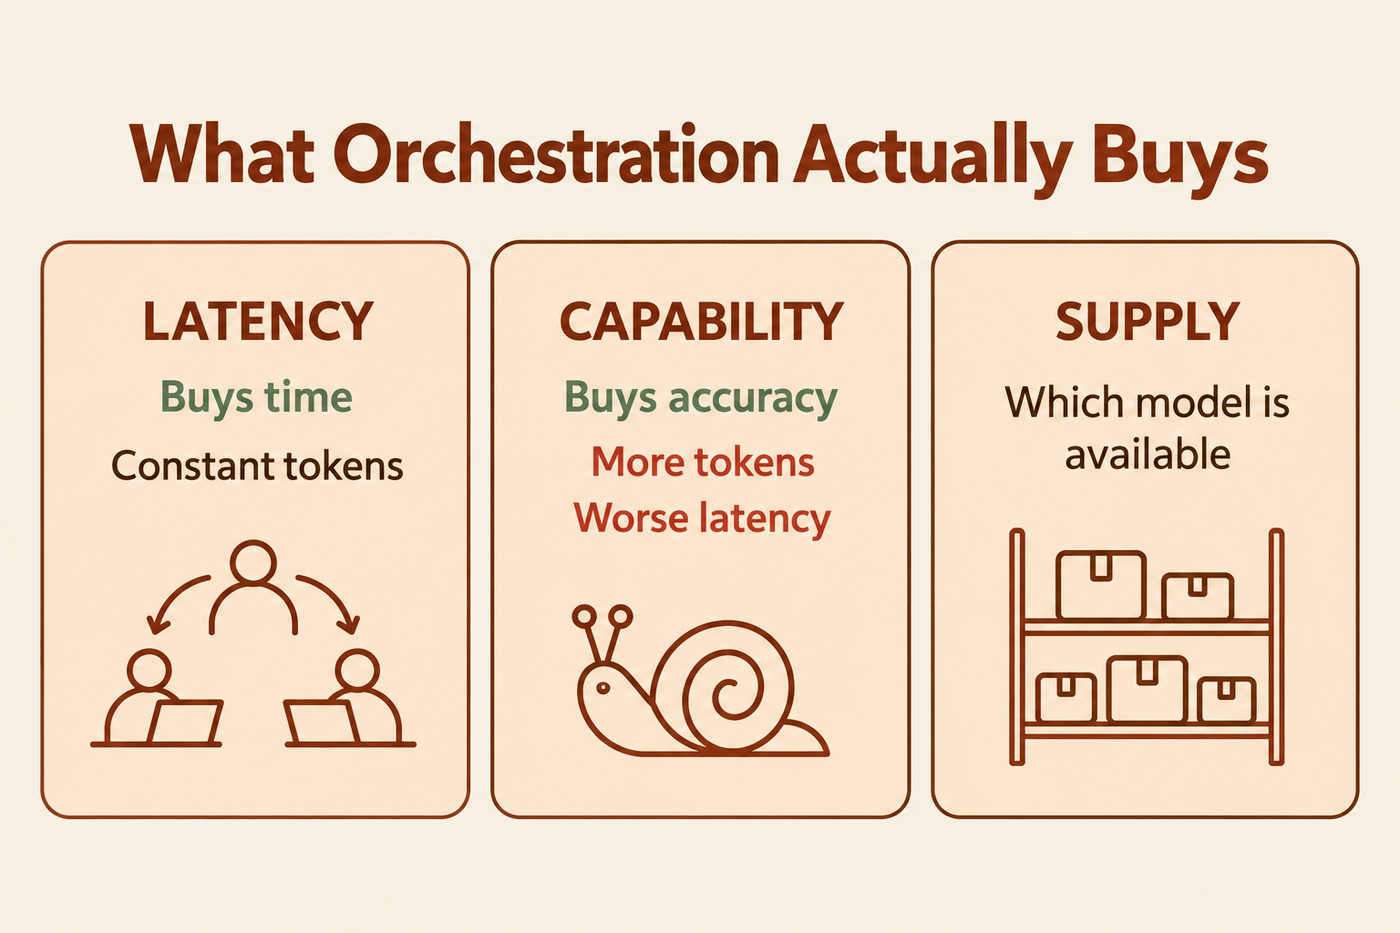
A task you give an AI assistant is a chain of model calls, and each call has its own best model. THALAMUS is a design for a router that picks the model again at every call: which one, how hard it thinks, how much of the conversation it sees and what runs beside it.
Abstract
AI models differ in intelligence, price, strengths and the topics they refuse. Routers usually pick one model per task and keep it to the end, even though a task is a chain of calls. Thalamus chooses again at every call.
At each decision point Jev, a small model that answers only in typed choices, describes the situation in under half a second. The router then prices every option in money, quota, cache and time, at the setting of one dial that runs from fast to smart, with nothing trained. The same read ranks the assistant’s own skills, recipes and plugins into a short list, and a nightly loop rewrites the descriptions Jev reads.
Because cached reading is so cheap, the router moves pieces of work and leaves whole conversations where they are. Version 4.1, 30 September 2026, is a design: it names eight tests, and none of them has run yet.
The secretary
The paper opens with a picture I like, a very smart secretary. However smart she is, she can’t answer every question herself, and she knows who can. The proof goes to a mathematician, the letter to a careful writer, the log of a break-in to someone who will read it instead of refusing. She also knows which binder of old procedures fits the job, even one filed under something else.
The thalamus in your brain does something similar. It passes each incoming signal to the part of the cortex built to handle it. That’s where the name comes from.
Four requests on one afternoon
The paper tests its ideas on four requests that arrive in the same assistant on the same afternoon: a proof in group theory, a short letter in Swahili, the log of a break-in full of real exploit code, and a 600,000-token contract to search for early-termination clauses.
No single model is right for all four. The proof wants the strongest reasoner. The letter wants the model that writes the best Swahili, which may well be a cheaper one. The log wants a model that will read it at all. When Hugging Face was broken into in July 2026, its team first sent the attack logs to hosted models, whose safety rules blocked the work, and then ran the forensics on an open model on their own machines.
Inside the contract request, the assistant plans, reads, notes each clause, checks the doubtful ones and writes the answer. The plan wants a strong model. Reading 600,000 tokens for one kind of clause is mechanical, and it splits into pieces that can be read at the same time. A router that chooses once per request pays the planner’s price on every one of those calls, and runs them one after another.
Read, then price
Jev is a decision model from TypeSafe AI, released in September 2026, and it can’t write text. It returns choices among up to 255 named options, scores and probabilities, each with a confidence. The vendor reports answers in 70 to 500 milliseconds, at a few cents per million input tokens. That’s cheap and quick enough to ask at every call.
Thalamus asks Jev about the task once per request (what kind of work, how hard, how urgent, one answer or many parts), about each step before it runs (how much thought, how much of the conversation), and about each result after it returns (done, retry, stuck, refused, needs a check).
Jev never names a model. It describes, and the prices decide. Each option gets one number made of its money cost (scaled by how fast a quota window is being used up), the time it adds to the slowest chain of the task, and the chance it fails times the cost of recovering. Before any pricing, vetoes rule out options that break privacy, the operator’s topic policy, the model’s window or a spent quota. When Jev is unsure, the router takes the cautious option.
Why it moves pieces of work
This is the part of the paper I find most useful. A model that has been reading a long conversation keeps it in a cache and re-reads it for a tenth of the normal price on most models, a twentieth on Claude Opus 5.5 and a fortieth on Claude Fable 5.1. A new model starts cold and pays in full, plus 1.25 times the price to write its own cache for five minutes, or twice the price for an hour.
So handing a running thread to a cheaper model only pays after a number of steps the paper calls N*. For a model five times cheaper at the usual cache prices, N* is about 2.9 steps. With the one-hour cache it’s about 4.8. When the expensive model is Opus 5.5, reading its cache at a twentieth, it rises to about 7.7. Oddly, the length of the conversation cancels out of the formula.
Most switch points don’t have this problem, because the new model starts on a short, fresh input anyway: one unit of work with its own brief, a single long tool result, a piece of work to check, the final answer. So the design picks freely at those points and leaves the main thread alone unless a long run of mechanical steps, a stuck step or a cold cache makes the move worth it. Long tool results get condensed by a cheap reader, with the raw result kept on disk in case a detail matters later. Checks go to a model from another family, so it doesn’t share the builder’s blind spots.
Finishing sooner
A chain is as slow as its length. The design plans a task as a graph, starts every unit whose inputs are ready, and gives the slowest chain the fast models. A call that runs slow gets a second copy on another provider, and the first answer back wins. In the contract example, twelve readers on two providers each read a 50,000-token piece at the same time, and a strong model combines their short lists. The paper marks the timings in that figure as illustrative.
The right skill for the job
New in version 4.1 is a section on the assistant’s own skills, recipes and plugins. Agents often start from scratch on a task a recipe already covers, and rarely notice that a loop written to check translations against their source would fit any check of an output against a target.
So the same Jev call that reads the task also ranks these enhancements. The agent gets a short list in order of probability: the fewest entries that together hold 80 per cent of it, never more than six, with “none of these fits” always among the options. The agent still decides which one to use, if any. Each night a loop looks at what the agent actually used, proposes small edits to the descriptions Jev reads, and keeps an edit only if it ranks the right ones higher on past tasks the edit never saw.
What changed, and what’s still open
This page used to describe the 3 September 2026 sketch, MAESTRO v0.2, a taxonomy of twelve orchestration mechanisms. The paper has since been rewritten from the ground up as a design for the next version of the router, with a new name and a new question: which AI should I ask, at each call?
It reports no results yet, only the eight tests of section 10. One of them runs the same tasks through Thalamus and through the single best model at the same cost, because one good model with an ordinary fallback list might give most of the benefit. Jev also belongs to a third party, and its speed and accuracy figures are the vendor’s own.
The implementation is part of Building Jarvis, an open series on persistent agents. Follow the work and contribute at github.com/globalcaos/tinkerclaw.
Read the paper
18 pages · v4.1 · 30 September 2026 · a router that chooses at every call
Everything on the site, by topic or date: Browse the Tinker Zone